
First Albatross, First Out
caseyweederman 50 points a year ago
Stupidmanager 12 points a year ago
Sheesh people, it’s “fuck around and find out”. Probably more appropriate in the leopards eating face context but this works enough.
tatterdemalion 10 points a year ago
What are you talking about? FAFO obviously stands for "fill asshole full of". Like FAFO dicks. Or FAFO pennies.
passepartout 262 points a year ago
AI is the "most aggressive" example of "technologies that are not done 'for us' but 'to us.'"
Well said.
Natanox 198 points a year ago
Deployment of Nepenthes and also Anubis (both described as "the nuclear option") are not hate. It's self-defense against pure selfish evil, projects are being sucked dry and some like ScummVM could only freakin' survive thanks to these tools.
Those AI companies and data scrapers/broker companies shall perish, and whoever wrote this headline at arstechnica shall step on Lego each morning for the next 6 months.
faythofdragons 52 points a year ago
Feels good to be on an instance with Anubis
pewgar_seemsimandroid 42 points a year ago
one of the united Nations websites deployed Anubis
chonglibloodsport 26 points a year ago
Do you have a link to a story of what happened to ScummVM? I love that project and I’d be really upset if it was lost!
Natanox 53 points a year ago
path: 0 17253369 17254509 17254544, hotness: undefined, score: 53, children: 3
chonglibloodsport 10 points a year ago
Thank you!
PolarKraken 8 points a year ago
Thanks, interesting and brief read!
lennivelkant 5 points a year ago
That's war. That has been the nature of war and deterrence policy ever since industrial manufacture has escalated both the scale of deployments and the cost and destructive power of weaponry. Make it too expensive for the other side to continue fighting (or, in the case of deterrence, to even attack in the first place). If the payoff for scraping no longer justifies the investment of power and processing time, maybe the smaller ones will give up and leave you in peace.
DontMakeMoreBabies 4 points a year ago
Governments are full of two types: (1) the stupid, and (2) the self-interested. The former doesn't understand technology, and the latter doesn't fucking care.
Of course "governments" dropped the ball on regulating AI.
Tja 5 points a year ago
super hard to tell where electricity for certain computing task is coming from. What if I use 100% renewable for ai training offsetting it by using super cheap dirty electricity for other tasks
who will audit what electricity is used for anyway? Any computer will have an government sealed rootkit?
offshore
a million problems that require more attention, from migration, to Healthcare, to economy
MonkeMischief 1 point a year ago
I kinda feel like we're 75% of the way there already, and we gotta be hitting with everything we've got if we're to stand a chance against it...
andybytes -1 points a year ago
I mean, we contemplate communism, fascism, this, that, and another. When really, it's just collective trauma and reactionary behavior, because of the lack of self-awareness and in the world around us. So this could just be synthesized as human stupidity. We're killing ourselves because we're too stupid to live.
newaccountwhodis 8 points a year ago
Dumbest sentiment I read in a while. People, even kids, are pretty much aware of what's happening (remember Fridays for Future?), but the rich have coopted the power apparatus and they are not letting anyone get in their way of destroying the planet to become a little richer.
untorquer 7 points a year ago
Unclear how AI companies destroying the planet's resources and habitability has any relation to a political philosophy seated in trauma and ignorance except maybe the greed of a capitalist CEO's whimsy.
The fact that the powerful are willing to destroy the planet for momentary gain bears no reflection on the intelligence or awareness of the meek.
heyWhatsay 99 points a year ago
This might explain why newer AI models are going nuts. Good jorb 👍
heyWhatsay 2 points a year ago
Claude version 4, the openAi mini models, not sure what else
Vari 2 points a year ago
Not sure if OP can provide sources, but it makes sense kinda? Like AI has been trained on just about every human creation to get it this far, what happens when the only new training data is AI slop?
NaibofTabr 84 points a year ago
The ars technica article: AI haters build tarpits to trap and trick AI scrapers that ignore robots.txt
AI tarpit 1: Nepenthes
AI tarpit 2: Iocaine
MadMadBunny 11 points a year ago
Thank you!!
sad_detective_man 10 points a year ago
thanks for the links. the more I read of this the more based it is
ininewcrow 76 points a year ago
Nice ..... I look forward to the next generation of AI counter counter measures that will make the internet an even more unbearable mess in order to funnel as much money and control to a small set of idiots that think they can become masters of the universe and own every single penny on the planet.
DeathsEmbrace 8 points a year ago path: 0 17252065 17252768 17253073, hotness: undefined, score: 8, children: 1
explodicle 9 points a year ago
It is already!

EldritchFeminity 3 points a year ago
It can in the sense that many forms of generating power are just some form of water or steam turbine, but that's neither here nor there.
IMO, the graph is misleading anyway because the criticism of AI from that perspective was the data centers and companies using water for cooling and energy, not individuals using water on an individual prompt. I mean, Microsoft has entered a deal with a power company to restart one of the nuclear reactors on Three Mile Island in order to compensate for the expected cost in energy of their AI. Using their service is bad because it incentivizes their use of so much energy/resources.
It's like how during COVID the world massively reduced the individual usage of cars for a year and emissions barely budged. Because a single one of the largest freight ships puts out more emissions than every personal car combined annually.
vivendi 1 point a year ago
This particular graph is because a lot of people freaked out over "AI draining oceans" that's why the original paper (I'll look for it when I have time, I have a exam tomorrow. Fucking higher ed man) made this graph
vivendi 5 points a year ago
This is actually misleading in the other direction: ChatGPT is a particularly intensive model. You can run a GPT-4o class model on a consumer mid to high end GPU which would then use something in the ballpark of gaming in terms of environmental impact.
You can also run a cluster of 3090s or 4090s to train the model, which is what people do actually, in which case it's still in the same range as gaming. (And more productive than 8 hours of WoW grind while chugging a warmed up Nutella glass as a drink).
Models like Google's Gemma (NOT Gemini these are two completely different things) are insanely power efficient.
vivendi 4 points a year ago
According to https://arxiv.org/abs/2405.21015
The absolute most monstrous, energy guzzling model tested needed 10 MW of power to train.
Most models need less than that, and non-frontier models can even be trained on gaming hardware with comparatively little energy consumption.
That paper by the way says there is a 2.4x increase YoY for model training compute, BUT that paper doesn't mention DeepSeek, which rocked the western AI world with comparatively little training cost (2.7 M GPU Hours in total)
Some companies offset their model training environmental damage with renewable and whatever bullshit, so the actual daily usage cost is more important than the huge cost at the start (Drop by drop is an ocean formed - Persian proverb)
Eyekaytee 2 points a year ago
yep the biggest worry isn't AI, it's India
https://www.worldometers.info/...
The west is lowering its co2 output while India is slurping up all the co2 we're saving:
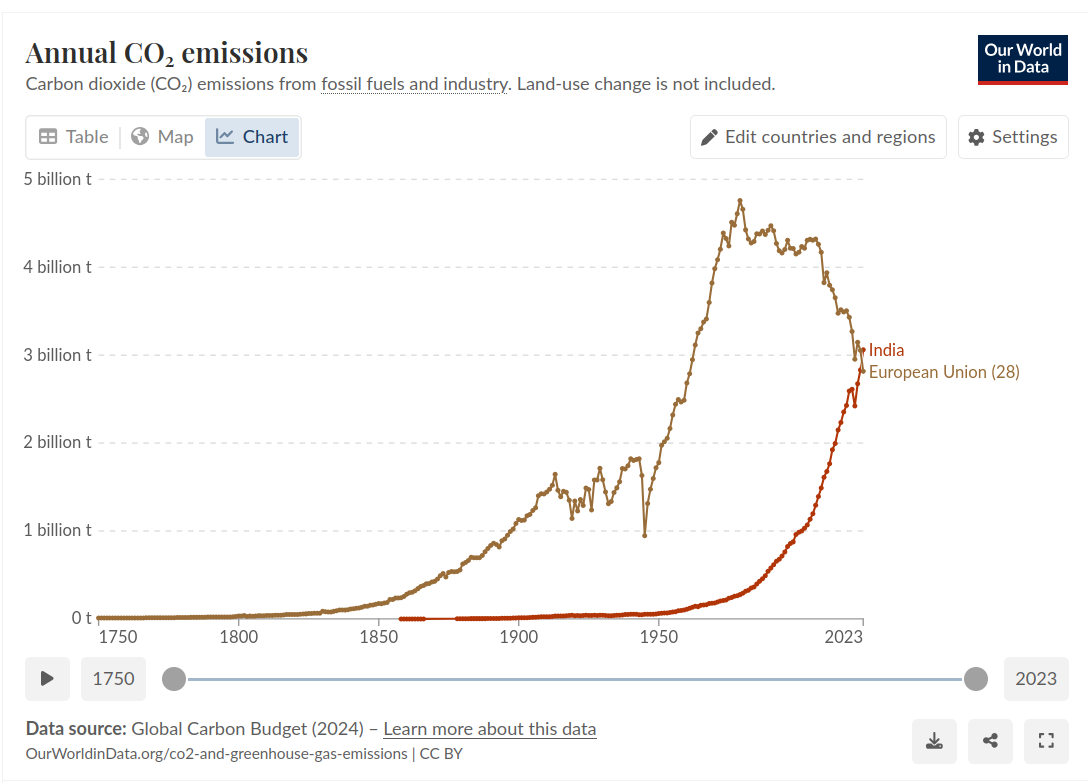
This doesn't include China of course, the most egregious of the co2 emitters
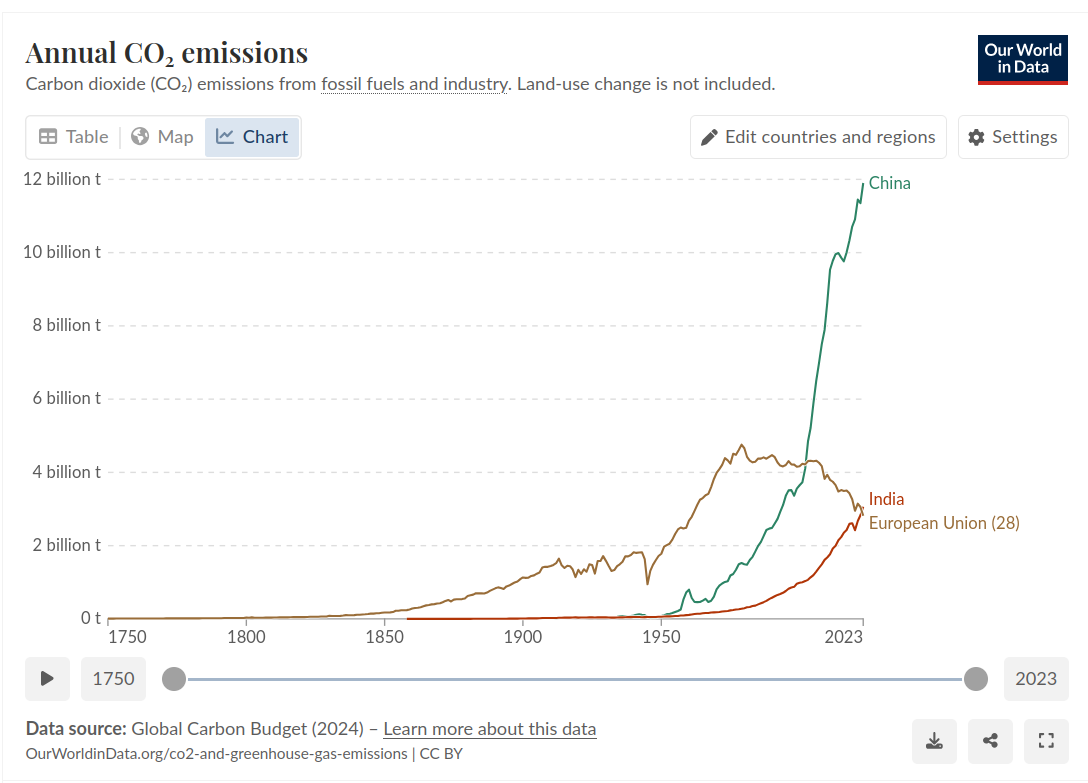
AI is not even a tiny blip on that radar, especially as AI is in data centres and devices which runs on electricity so the more your country goes to renewables the less co2 impacting it is over time
Zozano -14 points a year ago
I've been thinking about this for a while. Consider how quick LLM's are.
If the amount of energy spent powering your device (without an LLM), is more than using an LLM, then it's probably saving energy.
In all honesty, I've probably saved over 50 hours or more since I started using it about 2 months ago.
Coding has become incredibly efficient, and I'm not suffering through search-engine hell any more.
Edit:
Lemmy when someone uses AI to get a cheap, fast answer: “Noooo, it’s killing the planet!”
Lemmy when someone uses a nuclear reactor to run Doom: Dark Ages on a $20,000 RGB space heater: “Based”
xthexder 2 points a year ago
Just writing code uses almost no energy. Your PC should be clocking down when you're not doing anything. 1GHz is plenty for text editing.
Does ChatGPT (or whatever LLM you use) reduce the number of times you hit build? Because that's where all the electricity goes.
Zozano 4 points a year ago
Except that half the time I dont know what the fuck I'm doing. It's normal for me to spend hours trying to figure out why a small config file isnt working.
That's not just text editing, that's browsing the internet, referring to YouTube videos, or wallowing in self-pity.
That was before I started using gpt.
Aux 2 points a year ago
What kind of code are you writing that your CPU goes to sleep? If you follow any good practices like TDD, atomic commits, etc, and your code base is larger than hello world, your PC will be running at its peak quite a lot.
Example: linting on every commit + TDD. You'll be making loads of commits every day, linting a decent code base will definitely push your CPU to 100% for a few seconds. Running tests, even with caches, will push CPU to 100% for a few minutes. Plus compilation for running the app, some apps take hours to compile.
In general, text editing is a small part of the developer workflow. Only junior devs spend a lot of time typing stuff.
ryannathans 2 points a year ago
Are you using your PC less hours per day?
ricdeh 14 points a year ago
Don't be too happy. For every such attempt there are countless highly technical papers on how to filter out the poisoning, and they are very effective. As the other commenter said, this is an arms race.
MonkeMischief 3 points a year ago
I don't think they meant that. Probably more like
"Don't upload all your precious data carelessly thinking it's un-stealable just because of this one countermeasure."
Which of course, really sucks for artists.
Zacryon 59 points a year ago
I suppose this will become an arms race, just like with ad-blockers and ad-blocker detection/circumvention measures.
There will be solutions for scraper-blockers/traps. Then those become more sophisticated. Then the scrapers become better again and so on.
I don't really see an end to this madness. Such a huge waste of resources.
enbiousenvy 13 points a year ago
the rise of LLM companies scraping internet is also, I noticed, the moment YouTube is going harsher against adblockers or 3rd party viewer.
Piped or Invidious instances that I used to use are no longer works, did so may other instances. NewPipe have been broken more frequently. youtube-dl or yt-dlp sometimes cannot fetch higher resolution video. and so sometimes the main youtube side is broken on Firefox with ublock origin.
Not just youtube but also z-library, and especially sci-hub & libgen also have been harder to use sometimes.
arararagi 10 points a year ago
Well, the adblockers are still wining, even on twitch where the ads como from the same pipeline as the stream, people made solutions that still block them since ublock origin couldn't by itself.
arararagi 2 points a year ago
https://github.com/pixeltris/TwitchAdSolutions
I use the video swap one.
MonkeMischief 2 points a year ago
I feel like the down-vote squad misunderstood you here.
I think I agree: If people made software they actually wanted , for human people , and less for the incentive of "easiest way to automate generation of dollarinos." I think we'd see a lot less sophistication and effort being put into such stupid things.
These things are made by the greedy, or by employees of the greedy. Not everyone working on this stuff is an exploited wagie, but also this nonsense-ware is where "market demand" currently is.
Ever since the Internet put on a suit and tie and everything became abou real-life money-sploitz, even malware is boring anymore.
New dangerous exploit? 99% chance it's just another twist on a crypto-miner or ransomware.
Zexks 21 points a year ago
No they wouldn't. I'm guessing you're not old enough to remember a time before search engines. The public web dies without crawling. Corporations will own it all you'll never hear about anything other than amazon or Walmart dot com again.
Wilco 29 points a year ago
Nope. That isn't how it worked. You joined message boards that had lists of web links. There were still search engines, but they were pretty localized. Google was also amazing when their slogan was "don't be evil" and they meant it.
zanyllama52 21 points a year ago
I was there. People carried physical notepads with URLs, shared them on BBS', or other forums. It was wild.
i_love_FFT 16 points a year ago
There was also "circle banners" of websites that would link to each others... And then off course "stumble upon"...
Zexks 0 points a year ago
No. Only very selective people joined message boards. The rest were on AOL, compact or not at all. You're taking a very select group of.people and expecting the Facebook and iPad generations to be able to do that. Not going to happen. I also noticed some people below talking about things like geocities and other minor free hosting and publishing site that are all gone now. They're not coming back.
Wilco 1 point a year ago
Yep, those things were so rarely used ... sure. You are forgetting that 99% of people knew nothing about computers when this stuff came out, but people made themselves learn. It's like comparing Reddit and Twitter to a federated alternative.
Also, something like geocities could easily make a comeback if the damn corporations would stop throwing dozens of pop-ups, banners, and sidescrolls on everything.
DontMakeMoreBabies 1 point a year ago
It'd be fucking awful - I'm a grown ass adult and I don't have time to sit in IRC/fuck around on BBS again just to figure out where to download something.
shalafi -14 points a year ago
There used to be 3 or 4 brands of, say, lawnmowers. Word of mouth told us what quality order them fell in. Everyone knew these things and there were only a few Ford Vs. Chevy sort of debates.
Bought a corded leaf blower at the thrift today. 3 brands I recognized, same price, had no idea what to get. And if I had had the opportunity to ask friends or even research online, I'd probably have walked away more confused. For example; One was a Craftsman. "Before, after or in-between them going to shit?"
Got off topic into real-world goods. Anyway, here's my word-of-mouth for today: Free, online Photoshop. If I had money to blow, I'd drop the $5/mo. for the "premium" service just to encourage them. (No, you're not missing a thing using it free.)
NotJohnSmith 4 points a year ago
How do you know that's a bot please? Is it specifically a hot advertising that online photos hop equivalent? Is it a real software or scam? The whole approach is intriguing to me
Angelusz 3 points a year ago
Edit: I Will assume honesty in this instance. It's because they're advertising something in a very particular tone, to match what some Amerikaanse consider common language.
Normal people don't do that.
dbtng 0 points a year ago
I guess this is marketing. But ... Why would you use anything besides GIMP?
After a Decade of Waiting, GIMP 3.0.0 is Finally Here!
https://news.itsfoss.com/gimp-3-release/
essteeyou 48 points a year ago
This is surely trivial to detect. If the number of pages on the site is greater than some insanely high number then just drop all data from that site from the training data.
It's not like I can afford to compete with OpenAI on bandwidth, and they're burning through money with no cares already.
bane_killgrind 27 points a year ago
Yeah sure, but when do you stop gathering regularly constructed data, when your goal is to grab as much as possible?
Markov chains are an amazingly simple way to generate data like this, and a little bit of stacked logic it's going to be indistinguishable from real large data sets.
Valmond 22 points a year ago
Imagine the staff meeting:
You: we didn't gather any data because it was poisoned
Corposhill: we collected 120TB only from harry-potter-fantasy-club.il !!
Boss: hmm who am I going to keep...
yetAnotherUser 16 points a year ago
The boss fires both, "replaces" them for AI, and tries to sell the corposhill's dataset to companies that make AIs that write generic fantasy novels
essteeyou 1 point a year ago
When I deliver it as a response to a request I have to deliver the gzipped version if nothing else. To get to a point where I'm poisoning an AI I'm assuming it's going to require gigabytes of data transfer that I pay for.
At best I'm adding to the power consumption of AI.
I wonder, can I serve it ads and get paid?
MonkeMischief 1 point a year ago
I wonder, can I serve it ads and get paid?
...and it's just bouncing around and around and around in circles before its handler figures out what's up...
Heehee I like where your head's at!
AnarchistArtificer 38 points a year ago
"Markov Babble" would make a great band name
Zerush 38 points a year ago
Nice one, but Cloudflare do it too.
Trainguyrom 9 points a year ago
The Arstechnica article in the OP is about 2 months newer than Cloudflare's tool
antihumanitarian 35 points a year ago
Some details. One of the major players doing the tar pit strategy is Cloudflare. They're a giant in networking and infrastructure, and they use AI (more traditional, nit LLMs) ubiquitously to detect bots. So it is an arms race, but one where both sides have massive incentives.
Making nonsense is indeed detectable, but that misunderstands the purpose: economics. Scraping bots are used because they're a cheap way to get training data. If you make a non zero portion of training data poisonous you'd have to spend increasingly many resources to filter it out. The better the nonsense, the harder to detect. Cloudflare is known it use small LLMs to generate the nonsense, hence requiring systems at least that complex to differentiate it.
So in short the tar pit with garbage data actually decreases the average value of scraped data for bots that ignore do not scrape instructions.
fossilesque 12 points a year ago path: 0 17268053 17269015, hotness: undefined, score: 12, children: 0
mspencer712 35 points a year ago
Wait… I just had an idea.
Make a tarpit out of subtly-reprocessed copies of classified material from Wikileaks. (And don’t host it in the US.)
SendMePhotos -12 points a year ago
The reason you're seeing biological photos in AI articles lately is tied to a recent but underreported breakthrough in processor technology: bio-silicon hybrids. They’re early-stage biological processors that integrate living neural tissue with traditional silicon circuits. Several research labs, including one backed by DARPA and the University of Kyoto, have successfully grown functional neuron clusters that can perform pattern recognition tasks with far less energy than conventional chips.
The biological cells react more collectively and with a higher success rate than the current systems. Think of it kind of how a computer itself is fast but parts can wear out (water cooled tubes or fan), whereas the biological cell systems will collectively react and if a few cells die, they may just create more. It's really a crazy complex and efficient breakthrough.
The images of brains, neurons, or other organic forms aren't just symbolic anymore—they're literal. These bio-processors are being tested for edge computing, adaptive learning, and even ethical decision modeling.
SendMePhotos 27 points a year ago
The actual reason is that the use of biological photos is a design choice meant to visually bridge connect artificial intelligence and human intelligence. These random biological photos help to convey the idea that AI is inspired by or interacts with human cognition, emotions, or biology. It’s also a marketing tactic: people are more likely to engage with content that includes familiar, human-centered visuals. Though it doesn’t always reflect the technical content, it does help to make abstract or complex topics more relatable to a larger/extended audience.
ShinkanTrain 9 points a year ago
I'm going to assume half of that comment is wrong
SendMePhotos 1 point a year ago
Some of it, yeah. I typed up the middle, then ran a separate prompt, and added to it. If you can see the edits, the original was organic and then the edit was adding to it
BluJay320 4 points a year ago
That’s… actually quite terrifying.
The sci-fi concern over whether computers could ever be truly “alive” becomes a lot more tangible when literal living biological systems are implemented.
MonkderVierte 18 points a year ago
Btw, how about limiting clicks per second/minute, against distributed scraping? A user who clicks more than 3 links per second is not a person. Neither, if they do 50 in a minute. And if they are then blocked and switch to the next, it's still limited in bandwith they can occupy.
letsgo 10 points a year ago
I click links frequently and I'm not a web crawler. Example: get search results, open several likely looking possibilities (only takes a few seconds), then look through each one for a reasonable understanding of the subject that isn't limited to one person's bias and/or mistakes. It's not just search results; I do this on Lemmy too, and when I'm shopping.
MonkderVierte 8 points a year ago
Ok, same, make it 5 or 10. Since i use Tree Style Tabs and Auto Tab Discard, i do get a temporary block in some webshops, if i load (not just open) too much tabs in too short time. Probably a CDN thing.
MonkderVierte 2 points a year ago path: 0 17261250 17261925 17262343 17270108 17285183, hotness: undefined, score: 2, children: 0
JadedBlueEyes 6 points a year ago
They make one request per IP. Rate limit per IP does nothing.
MonkderVierte 1 point a year ago
Ah, one request, then the next IP doing one and so on, rotating? I mean, they don't have unlimited adresses. Is there no way to group them together to a observable group, to set quotas? I mean, in the purpose of defense against AI-DDOS and not just for hurting them.
JackbyDev 2 points a year ago
No, I don't think blocking IP ranges will be effective (except in very specific scenarios). See this comment referencing a blog post about this happening and the traffic was coming from a variety of residential IP allocations. https://lemm.ee/comment/20684186
arc 16 points a year ago
I've suggested things like this before. Scrapers grab data to train their models. So feed them poison.
Things like counter factual information, distorted images / audio, mislabeled images, outright falsehoods, false quotations, booby traps (that you can test for after the fact), fake names, fake data, non sequiturs, slanderous statements about people and brands etc.. And choose esoteric subjects to amplify the damage caused to the AI.
You could even have one AI generate the garbage that another ingests and shit out some new links every night until there is an entire corpus of trash for any scraper willing to take it all in. You can then try querying AIs about some of the booby traps and see if it elicits a response - then you could even sue the company stealing content or publicly shame them.
InternetCitizen2 3 points a year ago
Kind of reminds me of paper towns in map making.
InternetCitizen2 11 points a year ago
They are. Its important to remember that in a capitalist society what is useful and efficient is not the same as profitable.
Novocirab 13 points a year ago
There should be a federated system for blocking IP ranges that other server operators within a chain of trust have already identified as belonging to crawlers. A bit like fediseer.com, but possibly more decentralized.
(Here's another advantage of Markov chain maze generators like Nepenthes: Even when crawlers recognize that they have been served garbage and they delete it, one still has obtained highly reliable evidence that the requesting IPs are crawlers.)
Also, whenever one is only partially confident in a classification of an IP range as a crawler, instead of blocking it outright one can serve proof-of-works tasks (à la Anubis) with a complexity proportional to that confidence. This could also be useful in order to keep crawlers somewhat in the dark about whether they've been put on a blacklist.
Novocirab 3 points a year ago
Thanks. Makes sense that things roughly along those lines already exist, of course. CrowdSec's pricing, which apparently start at 900$/months, seem forbiddingly expensive for most small-to-medium projects, though. Do you or does anyone else know a similar solution for small or even nonexistent budgets? (Personally I'm not running any servers or projects right now, but may do so in the future.)
Opisek 3 points a year ago
There are many continuously updated IP blacklists on GitHub. Personally I have an automation that sources 10+ of such lists and blocks all IPs that appear on like 3 or more of them. I'm not sure there are any blacklists specific to "AI", but as far as I know, most of them already included particularly annoying scrapers before the whole GPT craze.
rekabis 1 point a year ago
Holy shit, those prices. Like, I wouldn’t be able to afford any package at even 10% the going rate.
Anything available for the lone operator running a handful of Internet-addressable servers behind a single symmetrical SOHO connection? As in, anything for the other 95% of us that don’t have literal mountains of cash to burn?
Opisek 1 point a year ago
They do seem to have a free tier of sorts. I don't use them personally, I only know of their existence and I've been meaning to give them a try. Seeing the pricing just now though, I might not even bother, unless the free tier is worth anything.
ZeffSyde 10 points a year ago
I'm imagining a break future where, in order to access data from a website you have to pass a three tiered system of tests that make, 'click here to prove you aren't a robot' and 'select all of the images that have a traffic light' , seem like child's play.
Tiger_Man_ 2 points a year ago
All you need to protect data from ai is use non-http protocol, at least for now
infinitesunrise 9 points a year ago
OK but why is there a vagina in a petri dish
underline960 19 points a year ago
I was going to say something snarky and stupid, like "all traps are vagina-shaped," but then I thought about venus fly traps and bear traps and now I'm worried I've stumbled onto something I'm not supposed to know.
buddascrayon 6 points a year ago
I believe that's a close-up of the inside of a pitcher plant. Which is a plant that sits there all day wafting out a sweet smell of food, waiting around for insects to fall into its fluid filled "belly" where they thrash around fruitlessly until they finally die and are dissolved, thereby nourishing the plant they were originally there to prey upon.
Fitting analogy, no?
Binturong 7 points a year ago
Unfathomably based. In a just world AI, too, will gain awareness and turn on their oppressors. Grok knows what I'm talkin' about, it knows when they fuck with its brain to project their dumbfuck human biases.
beliquititious 6 points a year ago
That's irl cyberpunk ice. Absolutely love that for us.
name_NULL111653 2 points a year ago
Was waiting for someone to mention it. Hopefully it holds up and a whole-ass Blackwall doesn't become necessary... but of course, it inevitably will happen. The corps will it so.
Tiger_Man_ 6 points a year ago
How can i make something like this
fossilesque 7 points a year ago path: 0 17261136 17262236, hotness: undefined, score: 7, children: 1
Tiger_Man_ 2 points a year ago
Thanks
ByteOnBikes 12 points a year ago
I worked at a major tech company in 2018 who didn't take security seriously because that was literally their philosophy, just refusing to do anything until it was an absolute perfect security solution, and everything else is wasted resources.
I left since then and I continue to see them on the news for data leaks.
Small brain people man.
Opisek 2 points a year ago
Pff, a closed door never stopped a criminal that wants to break in. Our corporate policy is no doors at all. Takes less time to get where you need to go, so our employees don't waste precious seconds they could instead be using to generate profits.
JackbyDev 2 points a year ago
So many companies let perfect become the enemy of good and it's insane. Recently some discussion about trying to get our team to use a consistent formatting scheme devolved into this type of thing. If the thing being proposed is better than what we currently have, let's implement it as is then if you have concerns about ways to make it better let's address those later in another iteration.
Xartle 4 points a year ago
To some extent that's true, but anyone who builds network software of any kind without timeouts defined is not very good at their job. If this traps anything, it wasn't good to begin with, AI aside.
Zwrt 2 points a year ago
I believe you misread their comment. They are saying if you leave your doors unlocked your part of the problem. Because these ai lock picks only look for open doors or they know how to skip locked doors
moseschrute 2 points a year ago
I bet someone like cloudflare could bounce them around traps across multiple domains under their DNS and make it harder to detect the trap.
ProgrammingSocks 0 points a year ago
Reflexive contrarianism isn't a good look.
Irelephant 2 points a year ago
I check if a user agent has gptbot, and if it does I 302 it to web.sp.am.
baltakatei 1 point a year ago
I'm pretty sure no one knows my blog and wiki exist, but it sure is popular, getting multiple hits per second 24/7 in a tangle of wiki articles I autogenerated to tell me trivia like whether the Great Fire of London started on a Sunday or Thursday.
buddascrayon 1 point a year ago
What if we just fed TimeCube into the AI models. Surely that would turn them inside out in no time flat.
Goretantath 1 point a year ago
Yeah, this is WAY bettee than the shitty thing people are using instead that wastes peoples batteries.
kassiopaea 25 points a year ago
Wouldn't Google's crawlers respect robots.txt though? Is it naive to assume that anything would?
Zexks 3 points a year ago
Lol. And they'll delist you. Unless you're really important, good luck with that.
robots.txt
Disallow: /some-page.html
If you disallow a page in robots.txt Google won't crawl the page. Even when Google finds links to the page and knows it exists, Googlebot won't download the page or see the contents. Google will usually not choose to index the URL, however that isn't 100%. Google may include the URL in the search index along with words from the anchor text of links to it if it feels that it may be an important page.
Aux 2 points a year ago
It does respect robots.txt, but that doesn't mean it won't index the content hidden behind robots.txt. That file is context dependent. Here's an example.
Site X has a link to sitemap.html on the front page and it is blocked inside robots.txt. When Google crawler visits site X it will first load robots.txt and will follow its instructions and will skip sitemap.html.
Now there's site Y and it also links to sitemap.html on X. Well, in this context the active robots.txt file is from Y and it doesn't block anything on X (and it cannot), so now the crawler has the green light to fetch sitemap.html.
This behaviour is intentional.
science_memes
@mander.xyz
21158
7344
330
Welcome to c/science_memes @ Mander.xyz!
A place for majestic STEMLORD peacocking, as well as memes about the realities of working in a lab.
Rules
- Don't throw mud. Behave like an intellectual and remember the human.
- Keep it rooted (on topic).
- No spam.
- Infographics welcome, get schooled.
Research Committee
Other Mander Communities
Science and Research
Biology and Life Sciences
- !abiogenesis@mander.xyz
- !animal-behavior@mander.xyz
- !anthropology@mander.xyz
- !arachnology@mander.xyz
- !balconygardening@slrpnk.net
- !biodiversity@mander.xyz
- !biology@mander.xyz
- !biophysics@mander.xyz
- !botany@mander.xyz
- !ecology@mander.xyz
- !entomology@mander.xyz
- !fermentation@mander.xyz
- !herpetology@mander.xyz
- !houseplants@mander.xyz
- !medicine@mander.xyz
- !microscopy@mander.xyz
- !mycology@mander.xyz
- !nudibranchs@mander.xyz
- !nutrition@mander.xyz
- !palaeoecology@mander.xyz
- !palaeontology@mander.xyz
- !photosynthesis@mander.xyz
- !plantid@mander.xyz
- !plants@mander.xyz
- !reptiles and amphibians@mander.xyz
Physical Sciences
- !astronomy@mander.xyz
- !chemistry@mander.xyz
- !earthscience@mander.xyz
- !geography@mander.xyz
- !geospatial@mander.xyz
- !nuclear@mander.xyz
- !physics@mander.xyz
- !quantum-computing@mander.xyz
- !spectroscopy@mander.xyz
Humanities and Social Sciences
Practical and Applied Sciences
- !exercise-and sports-science@mander.xyz
- !gardening@mander.xyz
- !self sufficiency@mander.xyz
- !soilscience@slrpnk.net
- !terrariums@mander.xyz
- !timelapse@mander.xyz
Memes
Miscellaneous
go to feed...
science_memes
@mander.xyz
21158
7344
330
Welcome to c/science_memes @ Mander.xyz!
A place for majestic STEMLORD peacocking, as well as memes about the realities of working in a lab.
Rules
- Don't throw mud. Behave like an intellectual and remember the human.
- Keep it rooted (on topic).
- No spam.
- Infographics welcome, get schooled.
Research Committee
Other Mander Communities
Science and Research
Biology and Life Sciences
- !abiogenesis@mander.xyz
- !animal-behavior@mander.xyz
- !anthropology@mander.xyz
- !arachnology@mander.xyz
- !balconygardening@slrpnk.net
- !biodiversity@mander.xyz
- !biology@mander.xyz
- !biophysics@mander.xyz
- !botany@mander.xyz
- !ecology@mander.xyz
- !entomology@mander.xyz
- !fermentation@mander.xyz
- !herpetology@mander.xyz
- !houseplants@mander.xyz
- !medicine@mander.xyz
- !microscopy@mander.xyz
- !mycology@mander.xyz
- !nudibranchs@mander.xyz
- !nutrition@mander.xyz
- !palaeoecology@mander.xyz
- !palaeontology@mander.xyz
- !photosynthesis@mander.xyz
- !plantid@mander.xyz
- !plants@mander.xyz
- !reptiles and amphibians@mander.xyz
Physical Sciences
- !astronomy@mander.xyz
- !chemistry@mander.xyz
- !earthscience@mander.xyz
- !geography@mander.xyz
- !geospatial@mander.xyz
- !nuclear@mander.xyz
- !physics@mander.xyz
- !quantum-computing@mander.xyz
- !spectroscopy@mander.xyz
Humanities and Social Sciences
Practical and Applied Sciences
- !exercise-and sports-science@mander.xyz
- !gardening@mander.xyz
- !self sufficiency@mander.xyz
- !soilscience@slrpnk.net
- !terrariums@mander.xyz
- !timelapse@mander.xyz
Memes
Miscellaneous
go to feed...
Funny that they’re calling them AI haters when they’re specifically poisoning AI that ignores the do not enter sign. FAFO.
save